Novum and Genius Sep 2024 Built it, with a friend's help on the server
A site-scoring tool that cut a day of lead research to 2–3 hours
In September 2024 I built a Python and OpenAI tool that read each prospect site overnight and kept only the ones worth pitching, for Novum's and Genius's link building.
The problem
Every link Novum sold was won by pitching a guest post to another site’s editor. Before anyone could pitch, someone had to check the sites. An assistant spent about 8 hours a day to find 300–500 sites worth pitching out of a list of 1,000–3,000 pulled from Ahrefs or Sales Navigator.
What I built
A small web app in Python and Flask, with upload, progress and dashboard pages:
- Upload a list of sites from Ahrefs or Sales Navigator.
- Scrape each site’s title, description and page text.
- Ask GPT (gpt-4o-mini) whether the site fits the outreach, and get back “proceed” or not.
- Export the sites worth pitching as a CSV for the team.
It ran overnight on 10,000–20,000 sites, by my own count. The tool only did the first pass. The assistants still picked the right person at each site and found the email by hand.
I built it in September 2024. The first runs in its logs are from 4 to 19 September 2024. A friend helped me set up the server.
Decisions
Only the first pass
I kept the tool to one job: drop the sites that would never take a pitch. Finding the right contact needs judgment about who runs a site, so that stayed with the assistants.
One list through the tool
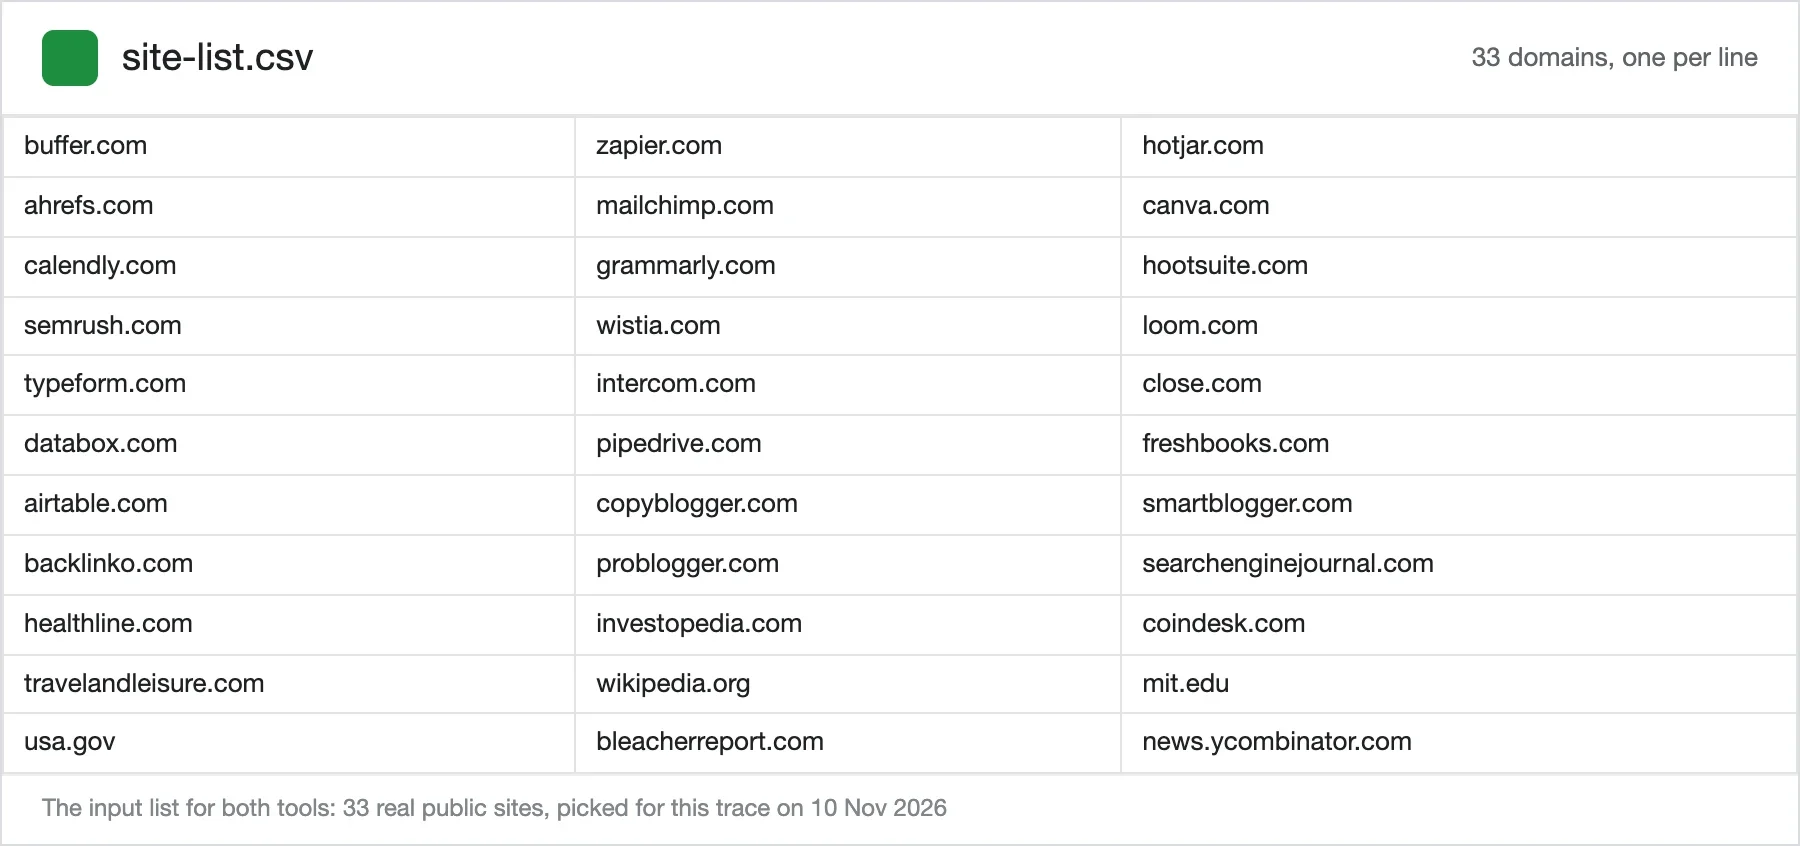
To show a run step by step, I put one list of 33 public sites through the September 2024 code again on 10 November 2026. The 2025 rebuild page runs the same list.
1. The list
A run started with a plain file, one domain per line, pulled from Ahrefs or Sales Navigator. The logged runs of 4 to 19 September 2024 used a sheet of 100 SaaS domains. For this page I made a list of 33 public sites: software companies with blogs, marketing blogs, and sites the tool should drop, such as health, finance, crypto, travel, news, .org, .edu and .gov.
2. Upload
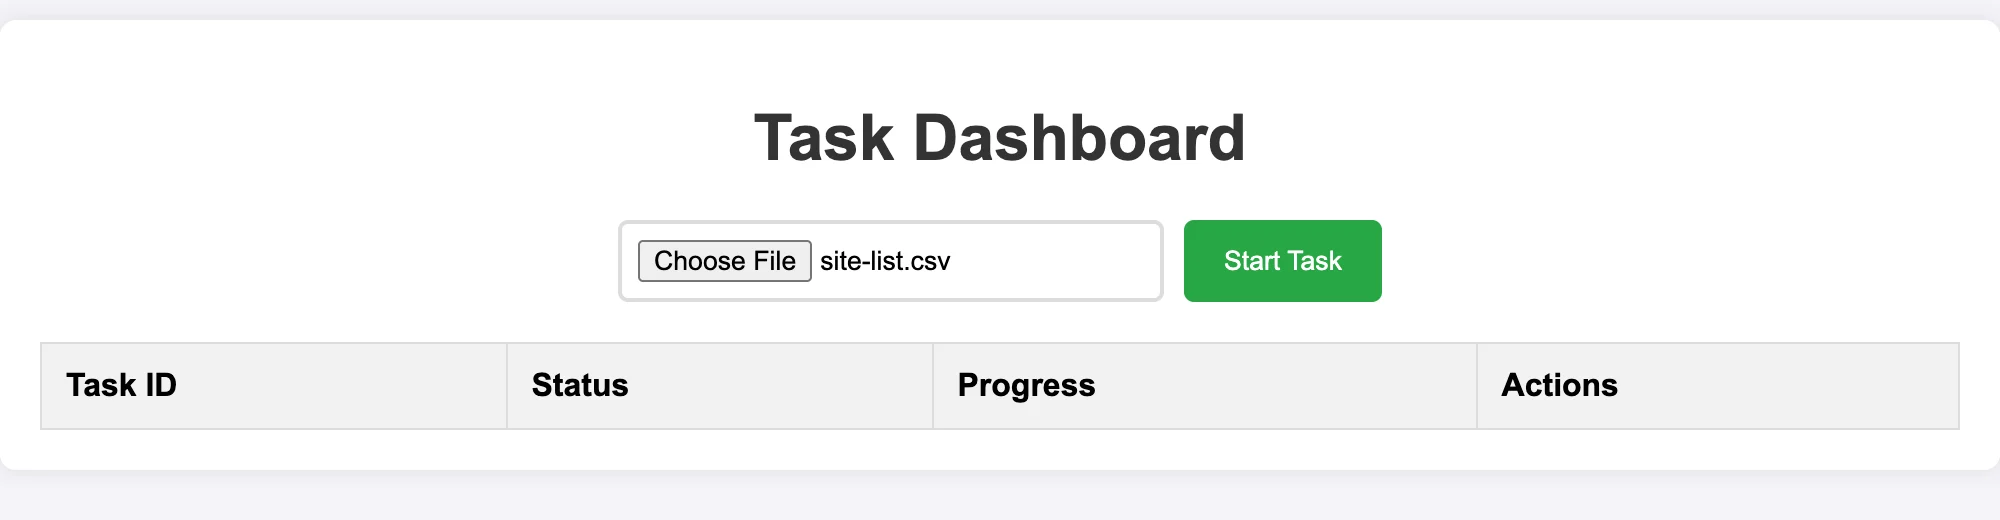
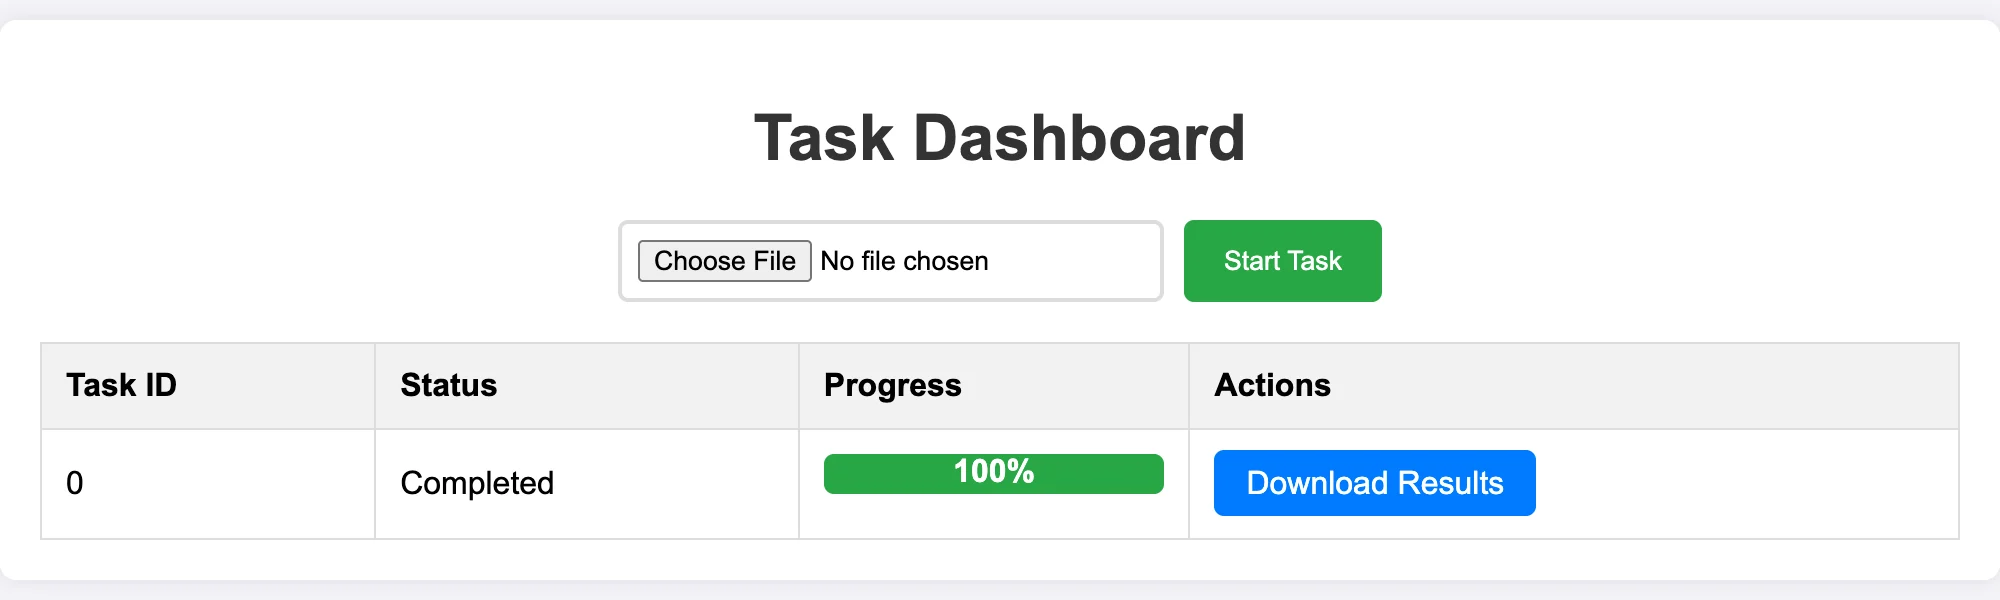
The app opens on one page, the task dashboard. I pick the file and press Start Task. It runs one list at a time. A second upload while a list is running gets “A task is already running.”
3. The run
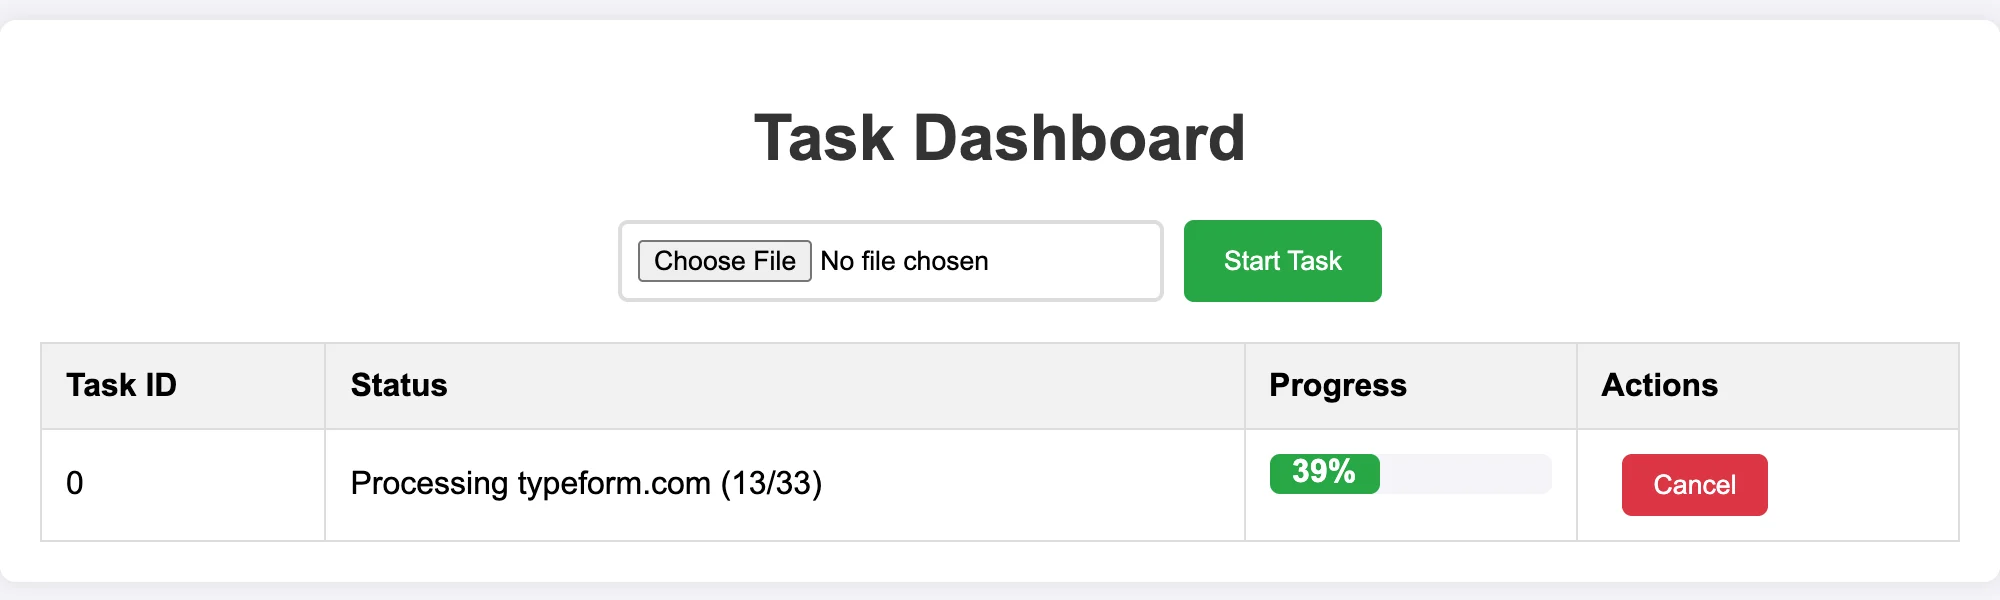
Each site goes through three checks. First GPT reads the bare address against ten blocked groups, such as news, health, finance, education and crypto. If none match, ScrapingBee fetches the homepage and keeps the first 500 characters of the title, description and text. Then GPT answers “Proceed” or “No Fit” for guest posting. The page shows which site it is on.
4. Done
When the last site is checked, the row turns to Completed and a Download Results button appears. With the stand-ins, the 33 sites took about 2 minutes, most of it the pauses the code puts between sites.
5. The CSV
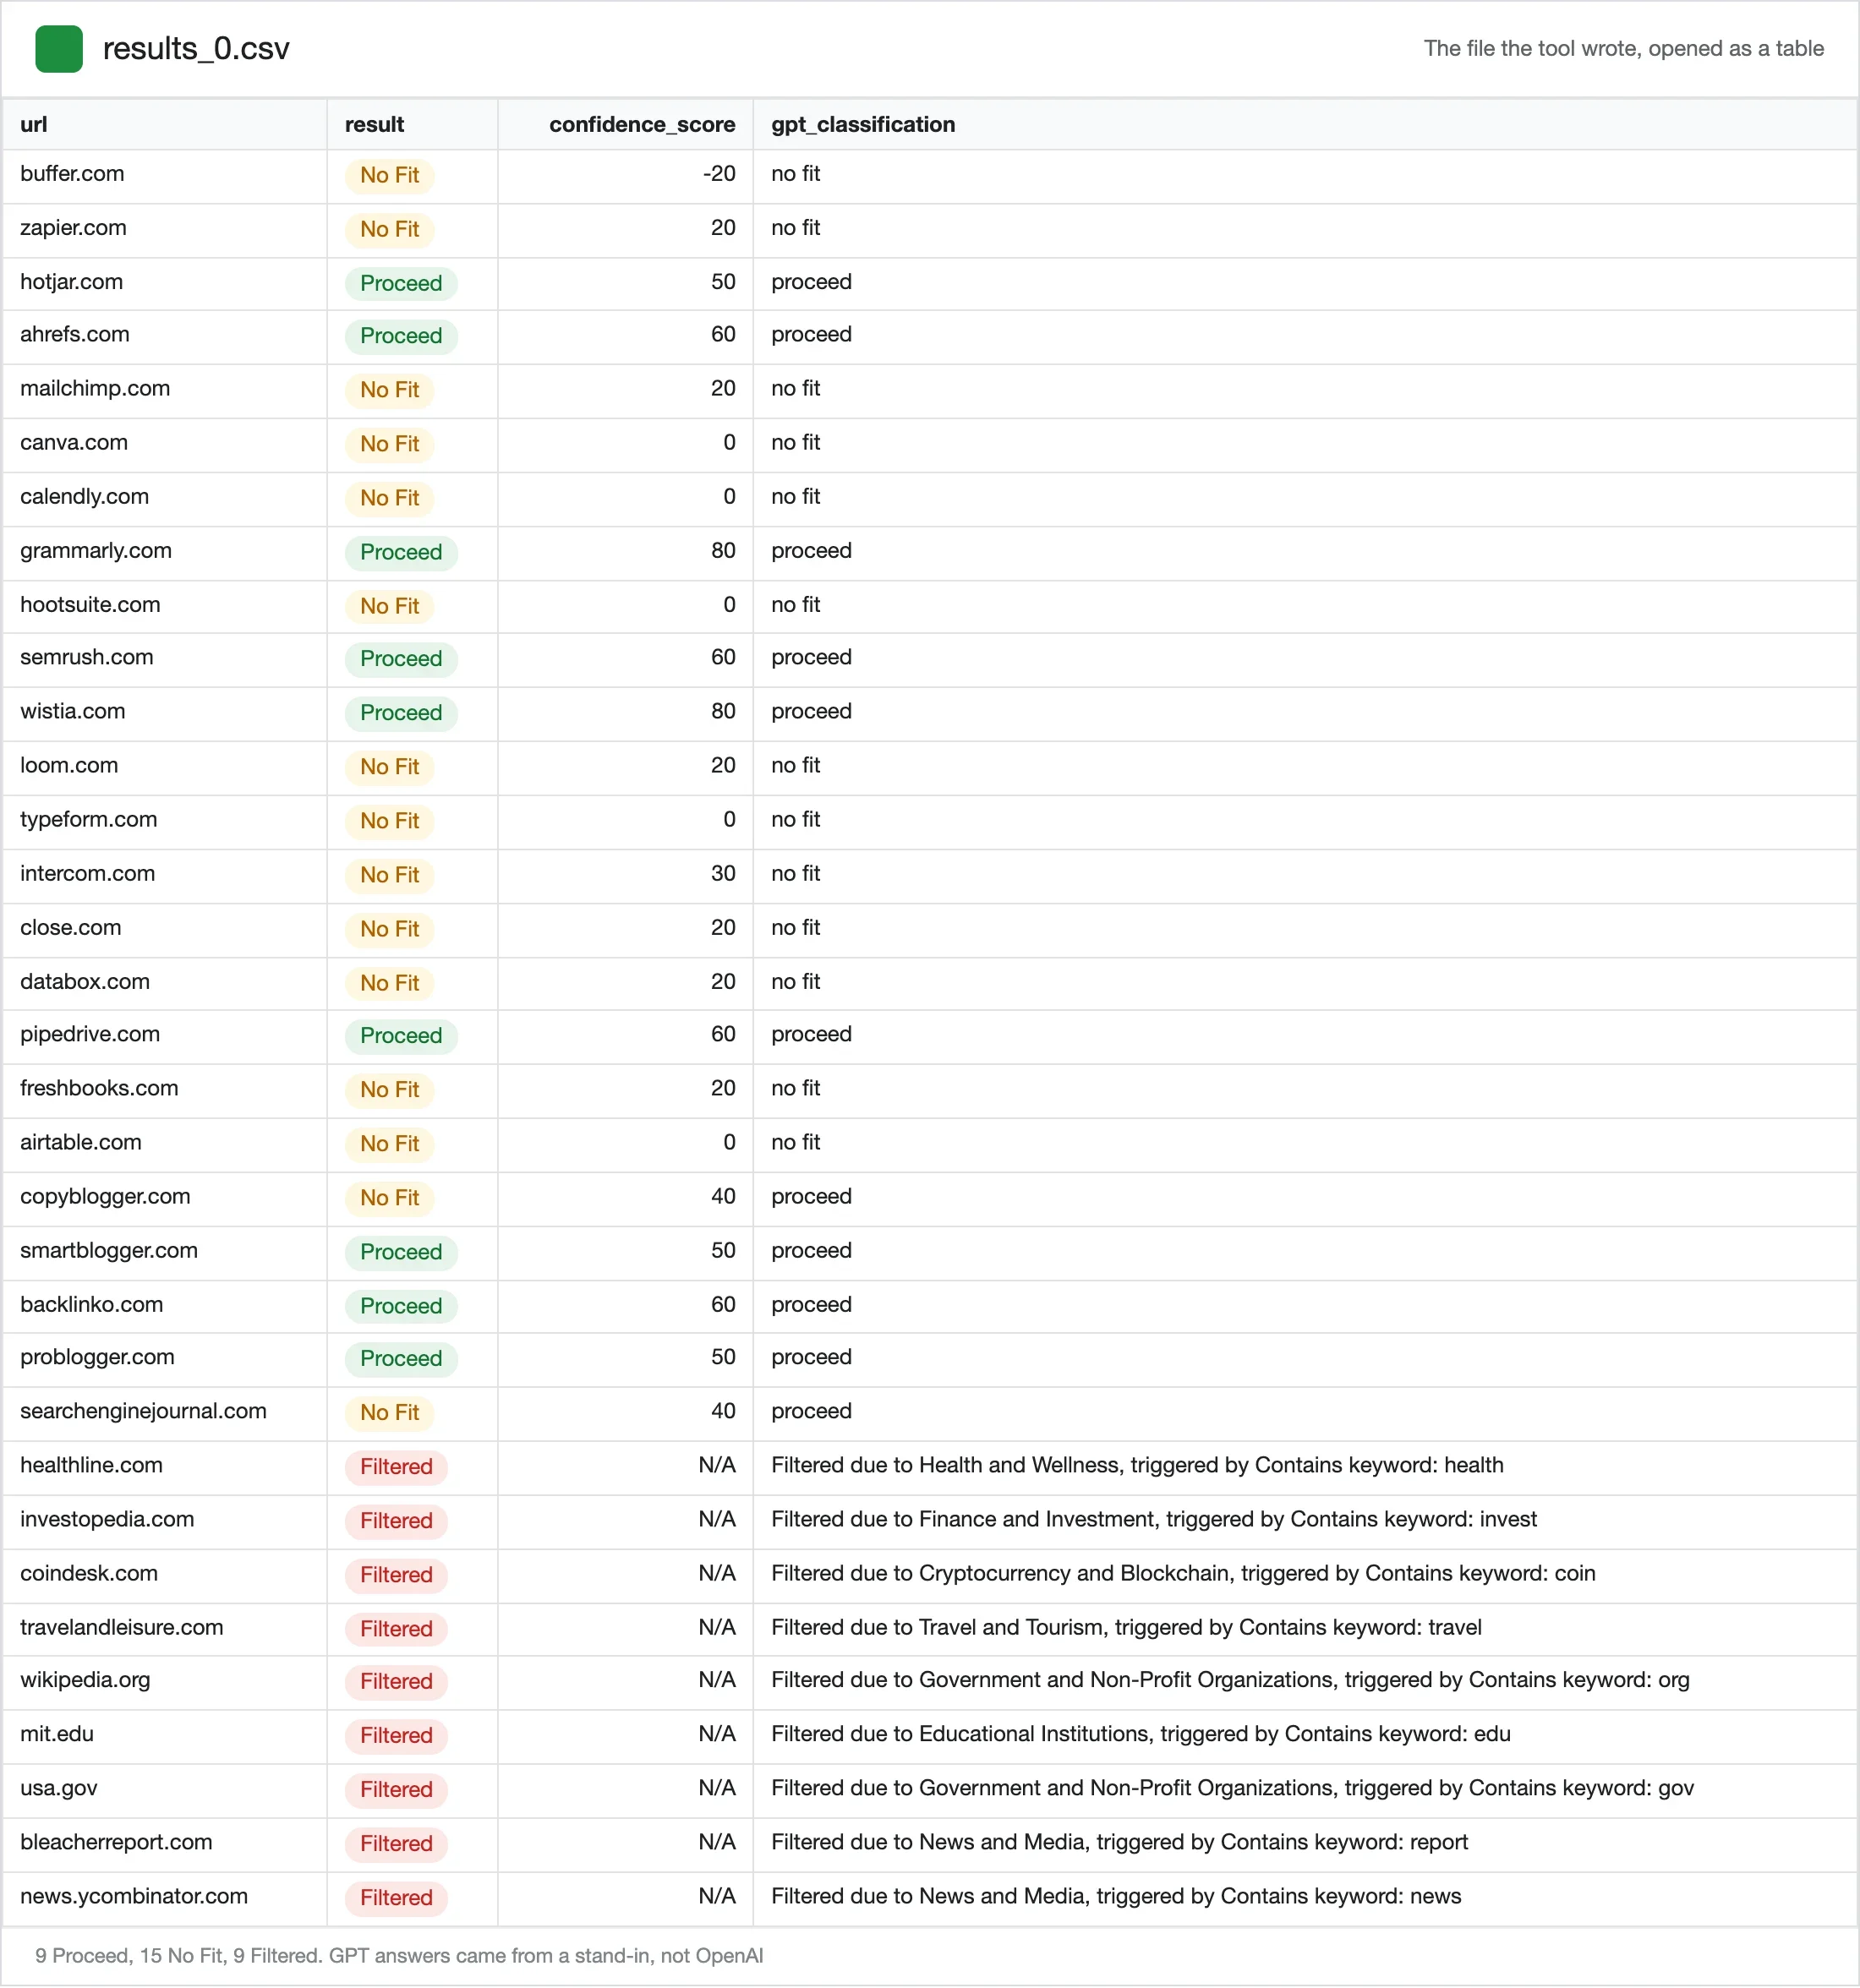
The file has one row per site: the result, a score and GPT’s answer. A keyword score adds points for words like “product”, “pricing” and “SaaS”, takes them away for “news” or “health”, and GPT’s “proceed” adds 50. A site needs 50 to pass. This list came out 9 Proceed, 15 No Fit and 9 Filtered. Copyblogger and Search Engine Journal got a “proceed” from GPT and still scored 40, so they stayed out. The assistants took the Proceed rows and found the contacts by hand.
The result
- A day of lead research went from about 8 hours to 2–3.
- The same tool fed both Novum’s link building and Genius’s.
- In late 2025 I rebuilt it as a full batch system. That is its own case study.